Every textbook on SDE discretisation gives you Euler-Maruyama first and then Milstein, with the note that Milstein is “first order” while Euler is “half order”, and moves on. What almost none of them tell you is when that upgrade is worth writing, when it does nothing at all, and when it fails to fix the problem you actually have.
The short version: the Milstein correction depends on the derivative of the volatility function. If your volatility doesn’t depend on the state, the extra term is identically zero and Milstein is Euler with more code. If it does, you get a genuine order improvement worth a factor of forty at fine grids. And on the model where you most want help — CIR near zero — it doesn’t help at all.
The two schemes
For a general SDE
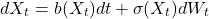
Euler-Maruyama is the obvious discretisation, replacing differentials with increments:
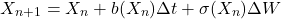
Milstein adds one term:
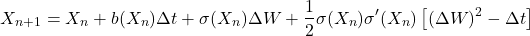
Look at what that term contains. It is the product of the volatility and its own derivative with respect to the state, multiplied by  , which has mean zero and represents the difference between realised and expected quadratic variation over the step.
The correction exists because Euler treats  as frozen across the interval. It isn’t — as
 moves during the step, so does its volatility. Milstein picks up the first-order effect of that drift in volatility via a stochastic Taylor expansion. That is the entire idea.
Case 1: when it works
Geometric Brownian motion,  , so
 . Non-zero, so the correction is live.
Because GBM has an exact solution, we can drive both schemes with the same Brownian path and compare each against the truth. That measures strong error — pathwise accuracy, 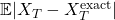 — which is the thing these convergence orders refer to.
| Steps | Euler | Milstein | Milstein advantage |
|---|---|---|---|
| 4 | 1.13234 | 0.20586 | 5.5× |
| 8 | 0.81853 | 0.10663 | 7.7× |
| 16 | 0.58653 | 0.05449 | 10.8× |
| 32 | 0.41696 | 0.02751 | 15.2× |
| 64 | 0.29544 | 0.01379 | 21.4× |
| 128 | 0.20847 | 0.00691 | 30.2× |
| 256 | 0.14799 | 0.00347 | 42.6× |
Two things worth reading off this table.
The measured orders are exactly what theory says. Doubling the steps cuts Euler’s error by  and Milstein’s by 2:
Euler order 0.49   Milstein order 0.99
Euler order 0.50   Milstein order 1.00
Euler order 0.50   Milstein order 1.00
Euler order 0.49   Milstein order 0.99
Half order and first order, measured rather than asserted. If you implement Milstein and see 0.5, the extra term is wrong.
The advantage compounds. At four steps Milstein is 5× better; at 256 it is 43× better. The gap widens because the errors decay at different rates — which means the finer your grid, the more the upgrade is worth. This is the opposite of the usual intuition that refinements matter most on coarse grids.
Case 2: when it does nothing
Now take arithmetic Brownian motion, or Vasicek, or Hull-White, or any model with constant volatility:
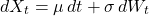
Here  . The Milstein term is
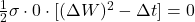 identically. Not small — zero.
Running both schemes on 200,000 paths:
max |Euler - Milstein| across 200k paths = 0.00e+00
Bit-for-bit identical. Milstein is Euler for these models, and any implementation effort spent on it is wasted.
This is worth internalising because a large fraction of rates modelling lives here. Vasicek, Hull-White, Ho-Lee, arithmetic Brownian motion — all constant-volatility, all immune to the upgrade. If someone tells you their Hull-White engine uses Milstein for accuracy, they have written a zero and multiplied by it.
The rule is simple: look at  before writing any code. If it’s zero, stop.
Case 3: when it doesn’t save you
CIR is where people reach for Milstein most, and where the story gets uncomfortable.
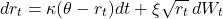
Here  , so
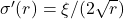 — non-zero, so the correction is live, and it simplifies neatly since
 . The Milstein term becomes
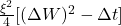 , with no square root in it at all.
The reason people want it: Euler on CIR generates negative rates, which is nonsense for a process that is provably non-negative. The hope is that Milstein fixes it.
Take parameters that violate the Feller condition —  ,
 ,
 , so
 against
 — which is where the trouble concentrates:
| Steps | Euler mean | Euler negative | Milstein mean | Milstein negative |
|---|---|---|---|---|
| 12 | 0.04113 | 26.51% | 0.04098 | 28.30% |
| 52 | 0.04002 | 16.32% | 0.03997 | 17.96% |
| 252 | 0.04021 | 10.06% | 0.04020 | 11.65% |
Exact answer: 0.04000.
Milstein doesn’t fix the negatives. It produces slightly more of them.
Both schemes get the mean right to three or four decimals — that is weak convergence, and it was never the problem. The problem is that a quarter of the steps at monthly frequency push the rate below zero, and adding the Milstein term makes that marginally worse rather than better, at every step size tested.
The reason is that the correction is a stochastic Taylor term designed to improve pathwise accuracy. It has no mechanism for enforcing a boundary. When  approaches zero, diverges, and the expansion Milstein is built on stops being valid precisely where you needed help.
The fix for CIR is not a higher-order scheme. It is a scheme that respects the boundary — full truncation, reflection, the Andersen QE scheme, or exact simulation via the non-central chi-square transition. Those work because they address the actual problem. Milstein addresses a different one.
Code
import numpy as np

def step(X, b, sigma, dsigma, dt, dW, milstein=False):
    """One step of Euler-Maruyama, or Milstein if the flag is set."""
    s = sigma(X)
    out = X + b(X)*dt + s*dW
    if milstein:
        out += 0.5*s*dsigma(X)*(dW**2 - dt)
    return out

# GBM: sigma(S) = 0.2*S, so dsigma(S) = 0.2  -> correction is live
gbm_sigma  = lambda S: 0.20*S
gbm_dsigma = lambda S: 0.20*np.ones_like(S)

# Vasicek: sigma(r) = 0.01 constant, so dsigma(r) = 0  -> correction is zero
vas_sigma  = lambda r: 0.01*np.ones_like(r)
vas_dsigma = lambda r: np.zeros_like(r)

# CIR: sigma(r) = xi*sqrt(r), and sigma*dsigma simplifies to xi^2/2
xi = 0.55
cir_sigma  = lambda r: xi*np.sqrt(np.maximum(r, 0.))
cir_dsigma = lambda r: xi/(2*np.sqrt(np.maximum(r, 1e-12)))
Before writing any of this, evaluate symbolically. That single check tells you whether the rest is worth doing.
The decision, in practice
Is zero? Then Euler and Milstein are the same scheme. Vasicek, Hull-White, arithmetic Brownian motion. Write Euler and move on.
Do you need pathwise accuracy? Milstein improves strong convergence from order 0.5 to 1.0, and the advantage grows as you refine. This matters for path-dependent payoffs — barriers, lookbacks, Asians — and for anything where individual trajectories carry meaning, such as exposure simulation.
Do you only need expectations? Both schemes are weak order 1 for these models. If you are pricing a European option, Euler at a finer grid is usually cheaper than Milstein at a coarser one, and much less code. The 43× table above measures pathwise error, not option prices.
Is your problem a boundary? Milstein will not help. Use a scheme built for the boundary.
The general point: Milstein is not a free upgrade, and it is not a fix for whatever is wrong with your simulation. It is a specific correction for a specific error term, and knowing which error you actually have is the whole of the decision.
Discretisation, strong versus weak convergence, and the numerical checks that tell you when a scheme is trustworthy are worked through from the ground up in the course modules.
Get the Quant Reference Card — four pages covering stochastic calculus, measure change, the models you’ll meet, discretisation, rates, credit and XVA. Free.