If you have read anything about risk-neutral pricing, you have met the symbol

and probably been told it is a “change of measure”. That is true and completely unhelpful. It looks like a derivative, it is not a derivative, and the notation actively obstructs the intuition.
Here is what it actually is: a set of weights. One number attached to every possible future scenario, telling you how much more or less likely that scenario is under one probability measure than under another. Nothing more exotic than that.
Two measures over the same scenarios
Start with the thing that confuses people. When we say the stock drifts at 12% in the real world and at the risk-free 4% under the pricing measure, we are not describing two different stocks or two different sets of possible futures.
The scenarios are identical. What changes is how much weight each one carries.
Under  — the real-world, or physical, measure — the paths where the stock does well are relatively likely, because the stock genuinely earns a risk premium. Under
 , those same paths are downweighted and the poor ones are upweighted, until the average return comes out at the risk-free rate.
The Radon-Nikodym derivative is exactly that reweighting function. Formally, if and agree on which events are impossible, there exists a strictly positive random variable  such that
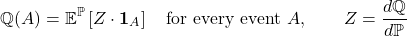
Read that second-to-last piece slowly: to get the -probability of anything, take the -probability and weight it by . That is the whole definition.
The two conditions that make it work
Two requirements, and both are doing real work.
Equivalence. The two measures must agree on impossibility:  if and only if
 . Reweighting can make a scenario very unlikely, but it cannot make an impossible scenario possible or vice versa. In finance this is what stops a change of measure from conjuring or destroying arbitrage — if a payoff is impossible in the real world, no pricing measure can pretend otherwise.
Positivity and normalisation.  everywhere, and
 . The second one is just the statement that is still a probability measure — total weight has to come to one.
Those two conditions are also your implementation checklist, and I will come back to that.
What it looks like for a stock
Take geometric Brownian motion with real-world drift  and volatility
 , and a risk-free rate
 . Define the market price of risk

which is the excess return per unit of volatility — how much you are being paid, in return terms, for each unit of risk you carry. Girsanov’s theorem then tells you the density is
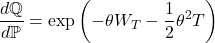
Look at the sign. Paths where the Brownian motion ended high — where the stock did well — get a negative exponent, so they are downweighted. Paths where it ended low get upweighted. Exactly the reweighting described above, written down.
With  ,
 and
 , we get
 .
Watching it work on a single set of paths
This is the part worth doing yourself, because it makes the abstraction concrete. Simulate two million stock paths under only, with the 12% drift. Never simulate under at all. Then just reweight.
First, the density has to be a valid one:
| Check | Value | Requirement |
|---|---|---|
 |
1.00011 | must be 1 |
| minimum | 0.10092 | must be > 0 |
| maximum | 6.27 | finite |
| median | 0.92311 | — |
Now take the same paths and compute the expected stock price two ways:
| Simulated | Theory | |
|---|---|---|
 |
112.7388 | 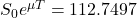 |
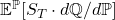 |
104.0882 | 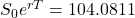 |
Identical paths. One multiplication by the weights, and a 12% drift becomes a 4% drift. That is the entire mechanism of risk-neutral pricing, and nothing was simulated twice.
Why it matters: 58% wrong without it
The obvious question is what happens if you skip the reweighting and just discount the real-world expectation. Price a one-year at-the-money call from the same paths:
| Method | Price |
|---|---|
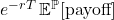 |
15.6715 |
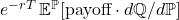 |
9.9209 |
| Black-Scholes | 9.9251 |
Discounting the real-world expectation overprices the option by 58%. Not a subtle correction — you would be quoting nearly two-thirds too much and every counterparty would happily trade against you.
The reweighted version matches Black-Scholes to four basis points, which is Monte Carlo noise on two million paths. Same paths, same code, one extra multiplication.
Where the intuition earns its keep
Once you see the density as weights, several things that look like separate topics collapse into one.
Girsanov is just the formula for the weights. The theorem says that if you reweight by 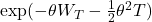 , then
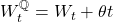 is a Brownian motion under the new measure. That is the drift-shifting machinery, but the object doing the work is the density.
Change of numéraire is the same idea with a different denominator. Switching from the money-market account to a  -bond gives you the forward measure, and the density is the ratio of the two numéraires. Same reweighting, different target.
Importance sampling is this used deliberately. In variance reduction you choose a measure that oversamples the region you care about, then divide the payoff by the density to correct the bias. That likelihood ratio is a Radon-Nikodym derivative. Pricing and variance reduction are the same operation aimed at different goals.
And it explains why disappears from option prices. The real-world drift is entirely absorbed into  , which is entirely absorbed into the weights. By the time you have reweighted, has cancelled. That is the formal reason an option price does not depend on whether you think the stock is going up.
The practical warning nobody mentions
The density is well behaved over one year. Over long horizons it is not, and this bites in real systems.
The exponent contains  , so the spread of the weights grows with the horizon. Measuring how concentrated the weight becomes:
| Horizon | Weight held by top 1% of paths | Largest single weight |
|---|---|---|
| 1 year | 2.7% | 7× |
| 5 years | 7.6% | 63× |
| 20 years | 29.5% | 1,528× |
At twenty years, one percent of your simulated paths carry thirty percent of the total weight, and a single path can be worth fifteen hundred times another. Your effective sample size has collapsed — you may have simulated a million paths but you are effectively averaging over a few thousand.
This is the standard reason long-dated exposure and XVA engines simulate directly under the measure they need rather than simulating under one and reweighting. Reweighting is elegant, exact in theory, and numerically unusable past a certain horizon. If you ever see a long-dated Monte Carlo with wild variance and no obvious bug, an over-stretched change of measure is a good first suspect.
Code
import numpy as np

S0, mu, r, sig, T, M = 100., 0.12, 0.04, 0.20, 1.0, 2_000_000
rng = np.random.default_rng(7)
Z = rng.standard_normal(M)

# simulate under P only
ST  = S0*np.exp((mu - 0.5*sig**2)*T + sig*np.sqrt(T)*Z)
W_T = np.sqrt(T)*Z

theta = (mu - r)/sig                              # market price of risk
dQdP  = np.exp(-theta*W_T - 0.5*theta**2*T)       # the density

assert abs(dQdP.mean() - 1) < 1e-3, "density must integrate to 1"
assert dQdP.min() > 0,              "density must be strictly positive"

print(f"E^P[S_T]           = {ST.mean():.4f}")
print(f"E^P[S_T * dQ/dP]   = {(ST*dQdP).mean():.4f}")

K = 100.
print(f"naive      = {np.exp(-r*T)*np.maximum(ST-K,0).mean():.4f}")
print(f"reweighted = {np.exp(-r*T)*(np.maximum(ST-K,0)*dQdP).mean():.4f}")
Those two assertions are the whole implementation test. If the mean of your density is not one, the normalising  term is wrong or missing. If any weight is negative or zero, you have not built a valid measure change at all — and both mistakes will quietly produce plausible-looking prices that are simply wrong.
The takeaway
The Radon-Nikodym derivative is a weight per scenario, not a rate of change. It exists whenever two measures agree on what is impossible, it must be positive and average to one, and in finance it is the object that converts a real-world drift into a risk-neutral one without touching a single simulated path.
Understand it as weights and Girsanov, change of numéraire, importance sampling and the disappearance of from option prices all become the same idea seen from four angles.
This sits directly between two other pieces worth reading alongside it: what a martingale actually is, since the density process is itself a martingale, and what the risk-neutral measure is, which is the measure this derivative constructs.
The measure change, the martingale machinery underneath it and the numerical checks that tell you when an implementation is right are worked through from the ground up in the course modules.
Get the Quant Reference Card — four pages covering stochastic calculus, measure change, the models you’ll meet, discretisation, rates, credit and XVA. Free.