There are two ways to price a European option, and they look nothing alike.
One is a **partial differential equation**: write down the Black-Scholes PDE, impose the payoff as a terminal condition, and integrate backwards through time on a grid. No randomness enters anywhere. It is deterministic numerical analysis.
The other is an **expectation**: simulate the stock under the risk-neutral measure, average the discounted payoff. No derivatives, no grid. It is probability.
Feynman-Kac is the theorem that says these are the same calculation.
The statement
Suppose  solves the PDE
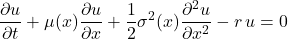
with terminal condition 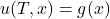 . Then
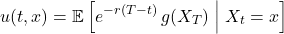
where  follows
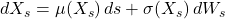 .
Read the correspondence term by term, because it is exact and it is the whole point:
| In the PDE | In the process |
|---|---|
coefficient of  |
the drift  |
coefficient of  |
the variance  |
the  term |
discounting at rate  |
terminal condition  |
the payoff |
Every piece of the equation has a probabilistic counterpart. The second-order term becomes volatility, the first-order term becomes drift, and the zeroth-order term becomes a discount factor.
Watching it happen
Price a one-year at-the-money call two ways, with no shared code between them.
**The PDE route.** Crank-Nicolson on a 400-point grid in spot and 400 steps in time, marching backwards from the payoff. At no point does a random number appear.
**The expectation route.** Four million simulated paths, discounted payoffs averaged. At no point does a derivative appear.
| Method | Value |
|---|---|
| PDE, finite differences backwards in time | 10.4481 |
 , Monte Carlo |
10.4393 ± 0.0144 |
| Black-Scholes closed form | 10.4506 |
The PDE lands within 0.0025 of the closed form; the Monte Carlo within 0.0113, comfortably inside its own two-standard-error band of 0.0144. Two computations with nothing in common, agreeing to the precision each one is capable of.
Why this is more than a curiosity
It is the bridge that makes derivatives pricing coherent, and three consequences follow directly.
**It explains why risk-neutral pricing works at all.** Black and Scholes derived a PDE from a hedging argument — build a delta-hedged portfolio, note it must earn the risk-free rate, and a PDE falls out. There is no probability in that derivation; it is pure replication. Feynman-Kac then tells you the solution to that PDE happens to be an expectation under a particular measure. **The expectation is a consequence of the hedging argument, not an assumption about anyone’s beliefs.** That is the answer to the perennial question of why we price under a measure nobody thinks is real.
**It tells you which numerical method to use.** The same price, two routes, and they have opposite strengths. PDE methods scale badly with dimension — one asset is easy, five is painful, ten is impossible — but they handle early exercise naturally, because at each grid point you simply compare continuation value with intrinsic. Monte Carlo is indifferent to dimension, but early exercise requires machinery like Longstaff-Schwartz. So: low-dimensional with optionality goes to the PDE; high-dimensional path-dependent goes to Monte Carlo. Feynman-Kac is what guarantees the choice is about efficiency and not about correctness.
**And it works in reverse.** Given a process, you can write down the PDE its expectations satisfy — the backward Kolmogorov equation. That is how you get a PDE for a model defined by an SDE, and it is how affine models produce their Riccati ODEs.
Where the conditions bite
The theorem needs the expectation to exist and behave, and that is not automatic.
The usual sufficient conditions are growth restrictions on ,  and the payoff — enough to guarantee the stochastic integral is a true martingale rather than a local one. When they fail, the correspondence breaks in a specific way: the PDE solution and the expectation stop agreeing, and the expectation is the one that is wrong.
This is not exotic. Models where the discounted price is a **strict local martingale** — CEV with  , certain stochastic volatility specifications — do exactly this. You get a finite PDE solution and an expectation that undershoots it, which in pricing terms means the risk-neutral expectation falls below the replication cost. That gap is the standard mathematical account of a bubble.
The practical implication: if your PDE and your Monte Carlo disagree by more than simulation error, do not assume one of them has a bug. Check whether your model satisfies the conditions first.
Code
import numpy as np
from scipy.linalg import solve_banded

S0, K, r, sig, T = 100., 100., 0.05, 0.20, 1.0
Smax, J, N = 400., 400, 400
dt = T/N
Sg = np.linspace(0, Smax, J+1)
V  = np.maximum(Sg - K, 0.)              # terminal condition = the payoff
j  = np.arange(1, J)

A = 0.25*dt*(sig**2*j**2 - r*j)
B = -0.5*dt*(sig**2*j**2 + r)
C = 0.25*dt*(sig**2*j**2 + r*j)
ab = np.zeros((3, J-1))
ab[0, 1:] = -C[:-1]; ab[1, :] = 1 - B; ab[2, :-1] = -A[1:]

for n in range(N):                        # march backwards in time
    rhs = A*V[0:J-1] + (1+B)*V[1:J] + C*V[2:J+1]
    lo, hi = 0.0, Smax - K*np.exp(-r*(n+1)*dt)
    rhs[0] += A[0]*lo; rhs[-1] += C[-1]*hi
    V[1:J] = solve_banded((1, 1), ab, rhs)
    V[0], V[J] = lo, hi

print(f"PDE : {np.interp(S0, Sg, V):.4f}")

rng = np.random.default_rng(3); M = 4_000_000
ST = S0*np.exp((r - 0.5*sig**2)*T + sig*np.sqrt(T)*rng.standard_normal(M))
pay = np.exp(-r*T)*np.maximum(ST - K, 0)
print(f"MC  : {pay.mean():.4f} +/- {1.96*pay.std(ddof=1)/np.sqrt(M):.4f}")
This is the single best cross-check you can build for a pricing library. The two methods share no code, no assumptions and no failure modes, so agreement between them is strong evidence and disagreement is informative. Comparing one implementation against a closed form only tells you whether you coded the same formula twice.
The takeaway
Feynman-Kac says a parabolic PDE and a discounted expectation are two descriptions of one object. The drift, the variance and the discount rate each appear in both, in exactly corresponding places.
It is what turns a hedging argument into a probability, what makes the choice between finite differences and Monte Carlo a question of efficiency rather than correctness, and — when its conditions fail — what tells you the two answers should genuinely differ.
The measure under which that expectation is taken is built by Girsanov’s theorem, and the second-order term in the PDE comes from Itô’s lemma.
PDE methods, Monte Carlo and the cross-checks between them are worked through from the ground up in the course modules.
Get the Quant Reference Card — four pages covering stochastic calculus, measure change, the models you’ll meet, discretisation, rates, credit and XVA. Free.