Someone hands you three correlations. A against B is 0.9. A against C is 0.9. B against C is 0.5.
Every number is between minus one and one. Every number is plausible on its own. Two assets strongly tied to a third, moderately tied to each other — nothing about that description should raise an eyebrow.
It is impossible. No three random variables have those correlations. And if you put the matrix into a risk system, it will report a portfolio whose variance is minus 0.032.
Correlation matrices live in a cone, not a box
The mistake is treating a correlation matrix as a collection of independent numbers, each free to roam in  . It is not. The entries constrain each other, and once you have fixed some of them the rest have much less freedom than the box suggests.
For three variables the constraint is explicit. Given  and
 , the third correlation must satisfy
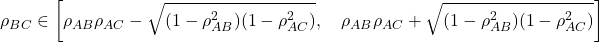
With 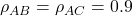 this collapses to
 .
The admissible range for the third number is 38% of the interval it appears to have. Anything below 0.62 is not a correlation, it is an arithmetic error wearing a correlation’s clothes.
 |
Smallest eigenvalue | Status |
|---|---|---|
 |
 |
impossible |
 |
 |
impossible |
 |
 |
impossible |
 |
 |
boundary |
 |
 |
valid |
The row worth staring at is the third. A positive, moderate, entirely ordinary-looking 0.5 is already outside the feasible set. The usual teaching example uses a glaring  , which makes the phenomenon look like something you would notice. You would not notice this one.
The general condition is that the matrix must be positive semidefinite: every eigenvalue non-negative. The three-variable formula above is just what that condition reduces to when  . For larger matrices there is no comparable closed form, which is exactly why the problem goes undetected.
The portfolio with negative variance
Positive semidefiniteness is not a technical nicety imported from linear algebra. It is the statement that every portfolio has non-negative variance.
Take the impossible matrix with  and ask for the eigenvector of its smallest eigenvalue:
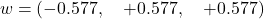
That is an equally weighted long-short book: short A, long B and C. Now compute its variance with 20% volatility on each name:
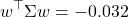
A risk system asked for the portfolio’s volatility will take the square root of that. In Python you get a nan that propagates silently into every downstream number. In C++ you may get a quiet garbage value. In a VaR engine you get a report.
This is the same failure mode as a CIR simulation taking the square root of a negative short rate, and the same as a local volatility surface taking the square root of a negative local variance. In all three cases a quantity that is non-negative by construction in the mathematics is negative in the implementation, and in all three the symptom appears several function calls away from the cause.
The practical trigger is usually Cholesky. Correlating random numbers in a Monte Carlo requires a Cholesky factor, Cholesky exists only for positive definite matrices, and the failure arrives as a terse error message in the middle of a simulation run. That error message is correct, it is the only safeguard in the chain, and it is routinely worked around rather than investigated.
Three ways valid data becomes an invalid matrix
Expert overrides and stress scenarios. A matrix is estimated from data, then someone adjusts a few entries. Risk committee wants the equity-credit correlation stressed to 0.9. A trader insists two names are more linked than history suggests. A scenario specifies what happens “if correlations go to one”. Each override is defensible in isolation, and each one moves the matrix a little further outside the cone. Nobody checks the eigenvalues afterwards because nobody thinks of a correlation matrix as a joint object.
Pairwise deletion. Assets have different histories — listings, delistings, holidays across markets, missing prints. The natural fix is to compute each pairwise correlation on whatever observations the two series share. That means every entry comes from a different sample, and there is no single dataset the resulting matrix is the correlation matrix of.
Simulating a one-factor equity structure with average pairwise correlation around 0.49:
| Assets | Days | Missing | Trials that fail | Worst eigenvalue |
|---|---|---|---|---|
| 30 | 500 | 30% | 0% |  |
| 30 | 120 | 30% | 100% |  |
| 60 | 120 | 40% | 100% |  |
| 100 | 60 | 50% | 100% |  |
With 500 days of history the method survives. Drop to 120 days — six months, a perfectly normal estimation window — and it fails in every single trial. The second row is worth isolating: 30 assets, around 59 usable observations per pair, comfortably more observations than assets. The failure there is not a sample-size problem. It is the pairwise construction itself.
More assets than history. The sample correlation matrix of  assets from
 observations has rank at most
 . If exceeds that, the matrix is singular by construction and no amount of clean data helps:
| Assets | Days | Rank | Zero or negative eigenvalues |
|---|---|---|---|
| 50 | 250 | 50 | 0 |
| 250 | 250 | 249 | 1 |
| 500 | 250 | 249 | 251 |
| 1000 | 250 | 249 | 751 |
A 500-name equity book estimated on a year of daily data has 251 directions in which the model reports exactly zero risk. Those are not low-risk portfolios. They are portfolios the estimator cannot see, and an optimiser hunting for low variance will find them and load up on them. This is the mechanism behind the notorious instability of unconstrained mean-variance optimisation on large universes, and it has nothing to do with the expected returns.
The two standard repairs, and what they cost
Once you have an invalid matrix you have to project it back into the cone. Two methods dominate.
Eigenvalue clipping. Decompose, set the negative eigenvalues to zero (or a small positive floor), reassemble, rescale the diagonal back to one. Four lines of code and it always works.
Higham’s nearest correlation matrix. Alternating projections between the set of positive semidefinite matrices and the set of matrices with unit diagonal, converging to the genuinely closest valid correlation matrix in Frobenius norm.
On a perturbed 12-asset matrix with a smallest eigenvalue of  :
| Method | Frobenius distance | Largest single entry change |
|---|---|---|
| Eigenvalue clipping |  |
 |
| Higham nearest |  |
 |
Higham is 17% closer and moves the worst entry 16% less. Clipping is not wrong — it produces a valid matrix — it just lands further away than necessary, and the extra distance is spread across entries nobody inspected.
Two things matter more than the choice between them.
The repair changes your correlations, and by a lot. The largest entry moves by around 0.12 to 0.14 here. If someone overrode a correlation to 0.9 for a stress scenario, the repaired matrix may well have moved it back, and the stress test is no longer testing what the committee asked for. Always diff the repaired matrix against the input and report the largest changes.
And the repair destroys the evidence. A pipeline that silently calls a fixing routine converts a loud, informative failure into a quiet one. The Cholesky error was telling you something true about your data construction. Fixing the matrix without logging the magnitude of the violation means the next person inherits a system that appears to work.
What to do
Check the smallest eigenvalue every time a correlation matrix is built or modified, and log it. One line, and it turns an invisible corruption into a number on a dashboard.
Use complete-case deletion or a model-based estimator rather than pairwise deletion. Pairwise is the convenient choice and it is the one that manufactures invalid matrices out of valid data.
Shrink before you repair. Ledoit-Wolf shrinkage towards a structured target fixes the  problem at its source by producing a full-rank estimate, rather than producing a singular one and patching it afterwards.
And when an override is applied, re-check afterwards and show the person who requested it what their override did to the rest of the matrix. They asked for one number to change. They are getting a different matrix.
The honest caveats
The three-correlation example is the smallest possible case and the constraint is tightest when the two known correlations are large. With 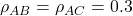 the admissible range for the third is
 , which is most of the box. The phenomenon is real at any size; the severity depends on how strong the existing links are. Highly correlated books are the dangerous ones, which is unhelpful, because highly correlated books are also the ones where correlation assumptions matter most.
The pairwise-deletion simulations use a one-factor structure with missingness completely at random. Real missingness is not random — it clusters around market closures and corporate events — and the direction of that bias depends on specifics I have not tested. The clean conclusion is that pairwise deletion fails readily on short windows, not a general law about how badly.
Higham beating clipping by 17% is one matrix. The ranking is guaranteed by construction, since Higham solves the minimisation that clipping only approximates, but the size of the gap is not. On a near-valid matrix both barely move anything and the choice is immaterial.
The same structural failure — an object that is non-negative by construction in the mathematics and negative in the implementation — shows up in a volatility surface interpolation, where a standard cubic spline produces a negative probability density.
Covariance estimation, shrinkage and the numerical conditions a risk model has to satisfy are worked through from the ground up in the course modules.
Get the Quant Reference Card — four pages covering stochastic calculus, measure change, the models you’ll meet, discretisation, rates, credit and XVA. Free.