Black-Scholes assumes prices move continuously. Between now and expiry, the stock drifts and wobbles, but it never teleports — to get from 100 to 90 it has to pass through 99, 98, and every value in between.
Markets don’t work like that. An earnings miss, a central bank surprise, a default: the price gaps, and the intervening values never trade.
A jump diffusion model is the smallest sensible fix. Keep the continuous Brownian part, add a second source of movement — sudden jumps arriving at random times with random sizes. Robert Merton wrote the jump diffusion model down in 1976, three years after Black-Scholes, and the Merton jump diffusion model remains the cleanest example of a volatility smile that emerges from first principles rather than being assumed.
The equation, term by term
The stock follows
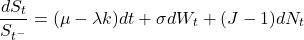
The first two terms are Black-Scholes. Everything new is in the last one.
 is a Poisson process counting jumps. They arrive at average rate
 per year. Set
 and you are saying “roughly one jump a year, but I don’t know when.”
 is the random jump size, a multiplier on the price. In Merton’s version
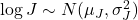 , so jumps can go either way but are drawn from a fixed distribution.
 with
 is a compensator. Jumps add expected return, so you subtract it back out of the drift to keep the discounted price a martingale. Without it you would silently move the forward every time you added jumps.
The  rather than
 matters more than it looks. The jump multiplies the price just before it happens. Prices are right-continuous, so at the instant of a jump is already the post-jump value and you need the pre-jump one to apply the multiplier. That subscript is the whole reason jump calculus differs from ordinary Itô.
Why anyone bothers: the smile falls out
Black-Scholes has one volatility, so every strike prices at the same implied vol — a flat line. Real option markets do not: out-of-the-money puts trade richer than the flat model says, producing the downward skew everyone calibrates to.
Jump diffusion produces that skew without being told to. Take a stock with 20% diffusive volatility and one jump a year averaging −10% with 15% dispersion. Price options across strikes, then back out the Black-Scholes implied vol of each:
| Strike | Moneyness | Merton implied vol | Black-Scholes |
|---|---|---|---|
| 80 | 0.80 | 27.70% | 20.00% |
| 90 | 0.90 | 26.82% | 20.00% |
| 95 | 0.95 | 26.45% | 20.00% |
| 100 | 1.00 | 26.12% | 20.00% |
| 105 | 1.05 | 25.83% | 20.00% |
| 110 | 1.10 | 25.58% | 20.00% |
| 120 | 1.20 | 25.18% | 20.00% |
Downward-sloping, from a model whose only volatility input was a flat 20%.
Two separate things are happening. The extra height everywhere comes from jumps adding variance. The slope comes from jumps being asymmetric — a −10% mean jump makes downside outcomes fatter than upside ones, so puts cost more.
The mechanism is in the moments of the return distribution:
| One-year log-return | Variance | Skewness | Excess kurtosis |
|---|---|---|---|
| Pure diffusion | 0.0400 | 0.000 | 0.000 |
| With jumps | 0.0725 | −0.397 | 0.565 |
Those are not tuned parameters. They are what a Poisson stream of normal jumps does to the moments, and the smile is those moments seen through the lens of implied volatility.
The closed form, and why it exists
Most models that fit a smile need Fourier inversion or simulation to price a vanilla. Merton’s does not, and the trick is worth seeing because it explains the model’s structure.
Condition on the number of jumps. If you knew exactly  jumps would occur before expiry, the total jump contribution would be a sum of normals — itself normal — so the whole model collapses to Black-Scholes with a shifted drift and a larger variance. You don’t know , but you know its distribution. So the price is a Poisson-weighted average of Black-Scholes prices:
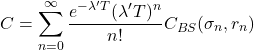
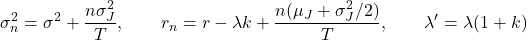
The sum converges in a handful of terms — the probability of ten jumps in a year when you expect one is negligible.
Two tests every implementation must pass
Switch the jumps off. Set  and the sum must collapse to a single Black-Scholes price. Not approximately:
Merton (lambda -> 0) = 10.450584
Black-Scholes        = 10.450584
Six decimals. If yours doesn’t do this, the compensator or the  shift is wrong.
Switch them on and simulate. The closed form must agree with brute force:
Merton closed form = 12.7613
Monte Carlo        = 12.8004
Black-Scholes      = 10.4506   (same sigma, no jumps)
Within simulation noise. Note the size of the jump contribution: 12.76 against 10.45 is a 22% higher price for an at-the-money call, from one extra term.
Code
import numpy as np
from math import factorial
from scipy.stats import norm

def bs(S, K, T, r, v):
    d1 = (np.log(S/K) + (r + 0.5*v*v)*T)/(v*np.sqrt(T))
    return S*norm.cdf(d1) - K*np.exp(-r*T)*norm.cdf(d1 - v*np.sqrt(T))

def merton(S, K, T, r, sig, lam, mJ, sJ, N=60):
    k    = np.exp(mJ + 0.5*sJ**2) - 1        # E[J-1]
    lam2 = lam*(1 + k)
    total = 0.0
    for n in range(N):
        r_n = r - lam*k + n*(mJ + 0.5*sJ**2)/T
        s_n = np.sqrt(sig**2 + n*sJ**2/T)
        w   = np.exp(-lam2*T)*(lam2*T)**n/factorial(n)
        total += w*bs(S, K, T, r_n, s_n)
    return total

S0, K, r, sig, T = 100., 100., 0.05, 0.20, 1.0
lam, mJ, sJ      = 1.0, -0.10, 0.15

print(f"lambda->0 : {merton(S0,K,T,r,sig,1e-9,mJ,sJ):.6f}  vs BS {bs(S0,K,T,r,sig):.6f}")
print(f"with jumps: {merton(S0,K,T,r,sig,lam,mJ,sJ):.4f}")
Where it works and where it runs out
It captures short-dated skew that pure diffusion cannot. A one-month crash-risk skew is very hard to fit with any continuous model — Brownian motion needs time to build asymmetry and over a month it barely can. Jumps produce fat tails instantly, which is why jump models earn their keep at the short end.
The skew flattens too fast with maturity. Real skews persist out to long expiries; Merton’s decays, because independent jumps average out over time by the central limit theorem. This is the standard reason desks reach for stochastic volatility, or combine both — the Bates model fits both ends of the maturity axis where neither ingredient alone can.
The jumps are unhedgeable in principle, and this is the deeper point. In Black-Scholes you replicate an option perfectly with stock and cash. You cannot delta-hedge a jump — by the time you would rebalance, the price has already gapped. That breaks the replication argument: the market becomes incomplete, there is no unique arbitrage-free price, and the model quietly assumes jump risk carries no premium (or prices it through the calibration). Not a flaw to be fixed so much as a true feature of markets that gap, and the entry point to a large part of modern derivatives theory.
The takeaway
One extra term, and a flat line becomes a smile. That is the whole reason jump diffusion is worth learning before anything more elaborate: it is the first model where the smile is a consequence of the dynamics rather than an input, and where the price does something no continuous process can.
Everything downstream — Lévy processes, Fourier pricing, the incompleteness that jump risk forces — generalises what happens in this one equation.
The stochastic calculus underneath this — Poisson processes, the jump-adjusted Itô formula, the measure change that makes it price — is what the course modules work through from the ground up, with the numerical checks that tell you when an implementation is right.
Get the Quant Reference Card — four pages covering stochastic calculus, measure change, the models you’ll meet, discretisation, rates, credit and XVA. Free.