Girsanov’s theorem is usually presented as a technical result about Brownian motion under a change of measure, and then applied without comment. That skips the part worth understanding.
Here is the whole thing in one sentence: **you can change the drift of a diffusion to anything you like, and you cannot touch the volatility at all.**
That asymmetry is not a limitation of the theorem. It is the reason risk-neutral pricing works, the reason option prices don’t depend on expected returns, and the reason volatility is the only parameter you can actually calibrate from market prices.
The statement
Take a Brownian motion  under a measure
 , and pick any adapted process
 . Define
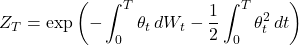
Then  is a valid Radon-Nikodym derivative, and under the measure
 it defines,
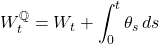
is a Brownian motion.
Read that last line carefully. The process  has a drift under — it is plus a drift term. Under it has none. **The same process, drifting under one measure and driftless under another.** Nothing about the paths changed; only how much weight each one carries.
What it does to a stock
Under , geometric Brownian motion with real-world drift:
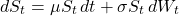
Choose  , the **market price of risk** — excess return per unit of volatility. Substituting
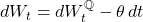 :
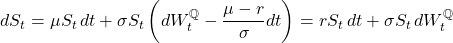
The  cancels. Same stock, same volatility, drift now
 .
Simulating 200,000 paths under with  ,
 ,
 , then reweighting rather than resimulating:
| Simulated | Theory | |
|---|---|---|
 |
112.7370 | 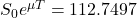 |
 |
104.0945 | 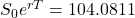 |
Why the volatility survives
This is the part that is usually asserted and rarely explained, and it has a clean reason.
Quadratic variation is a **pathwise** quantity. You compute  from the path itself — no probabilities enter the calculation anywhere. Each path already carries its own quadratic variation before you have decided which measure to use.
A change of measure reweights paths. It cannot alter a number that each path already holds.
Measuring it on those same 200,000 paths:
| Value | |
|---|---|
 per path, mean |
0.040003 |
 |
0.040000 |
 |
0.040003 |
 |
0.040010 |
A relative difference of  , which is Monte Carlo noise. The drift moved by 800 basis points and the volatility did not move at all.
So the division of labour is sharp: **drift is a property of the measure, volatility is a property of the path.** One is a modelling choice, the other is a fact about the trajectory.
Three consequences that follow immediately
**Option prices don’t depend on expected returns.** Everyone learns this and few people are told why. It is because is entirely absorbed into  , which is entirely absorbed into the weights. By the time you have changed measure, has cancelled algebraically. Your view on whether the stock is going up is irrelevant to the price of the option — not because the market disagrees with you, but because the drift is not in the formula.
**Volatility is the only thing you can calibrate.** Since  is the same under both measures, an implied volatility extracted from option prices is directly comparable with a realised volatility estimated from history. That comparison is meaningful. There is no equivalent for drift, because the -drift and the -drift are different objects by construction.
**Stochastic volatility models change fewer parameters than people expect.** In Heston, the vol-of-vol  and the correlation
 are diffusion coefficients, so Girsanov cannot touch them — they are identical under and . Only the variance drift shifts, and under Heston’s own specification that leaves exactly one free parameter. If a calibration produces a -measure far from the historical one, that is not a market phenomenon, it is a misspecification somewhere.
The condition, and what it is protecting you from
Girsanov needs to be a true martingale with  , and that is not automatic. The usual sufficient condition is **Novikov**:
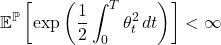
With constant this always holds, which is why textbook examples never run into trouble. With stochastic it can fail, and when it does, is only a local martingale,  , and is not a probability measure at all. Everything downstream is then meaningless while looking perfectly normal.
And the failure that arrives long before Novikov does
There is a practical limit that bites well before the mathematical one, and it is worth seeing.
Girsanov says you can shift the drift to anything. That is true and it is a statement about existence. Numerically, the weights spread out as grows, and past a point the reweighting stops working. Same 200,000 paths, pushing the target drift further and further:
| Target drift | |
 |
Largest weight | Weight in top 1% of paths |
|---|---|---|---|---|
| 6% | 0.10 | 1.0001 | 2× | 1.3% |
| 12% | 0.40 | 1.0003 | 5× | 2.7% |
| 25% | 1.05 | 1.0015 | 54× | 10.1% |
| 50% | 2.30 | 0.9935 | 1,475× | 48.3% |
| 100% | 4.80 | 0.3526 | 10,165× | 98.1% |
At a target drift of 100%, the weights sum to 0.35 instead of 1, and one percent of the paths carry ninety-eight percent of the total weight. The measure exists — Novikov is satisfied, constant — but your effective sample size has collapsed to a few hundred paths out of two hundred thousand. The estimator is worthless.
This is why long-dated exposure engines simulate directly under the measure they need instead of simulating once and reweighting. The change of measure is exact in theory and unusable past a certain distance. If you ever meet a Monte Carlo with wild variance and no obvious bug, an over-stretched Girsanov transformation is a good first place to look.
Code
import numpy as np

S0, mu, r, sig, T, N, M = 100., 0.12, 0.04, 0.20, 1.0, 2520, 200_000
dt = T/N
rng = np.random.default_rng(4)

logS = np.full(M, np.log(S0)); W = np.zeros(M); QV = np.zeros(M)
for _ in range(N):
    dW = np.sqrt(dt)*rng.standard_normal(M)
    dlog = (mu - 0.5*sig**2)*dt + sig*dW
    logS += dlog; W += dW; QV += dlog**2       # QV built from the path alone
ST = np.exp(logS)

theta = (mu - r)/sig
Z = np.exp(-theta*W - 0.5*theta**2*T)          # Girsanov density

print(f"E[Z]      = {Z.mean():.5f}")           # must be 1
print(f"E^P[S_T]  = {ST.mean():.4f}")          # drifts at mu
print(f"E^Q[S_T]  = {(ST*Z).mean():.4f}")      # drifts at r
print(f"E^P[QV]   = {QV.mean():.6f}")          # sigma^2 T
print(f"E^Q[QV]   = {(QV*Z).mean():.6f}")      # the same
Two checks worth building into any implementation. The density must average to one — if it doesn’t, the  term is wrong or missing. And the quadratic variation must be identical under both measures; if your reweighting changes it, you have altered the volatility, which Girsanov cannot do and your code should not either.
The takeaway
Girsanov’s theorem lets you set the drift to whatever you need and leaves the volatility exactly where it was. The drift lives in the measure and can be reweighted away; the volatility lives in the path and cannot.
That single asymmetry explains why vanishes from option prices, why implied and realised volatility are comparable quantities while – and -drifts are not, and why the whole apparatus of risk-neutral pricing is possible in the first place.
This completes a chain worth reading in order: what a martingale is, the Radon-Nikodym derivative that reweights the paths, and the risk-neutral measure that Girsanov constructs.
The measure change, the martingale machinery underneath it and the numerical checks that catch a broken implementation are worked through from the ground up in the course modules.
Get the Quant Reference Card — four pages covering stochastic calculus, measure change, the models you’ll meet, discretisation, rates, credit and XVA. Free.