Two sums over the same Brownian path. Chop  into
 pieces and add up the moves:
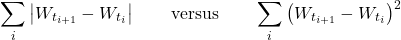
The first is total variation — the distance the path travels. The second is quadratic variation. They look like minor variations on each other and they behave in opposite ways, which turns out to be the reason stochastic calculus exists at all.
The measurement
Same path, refined grid, both sums computed at each resolution:
| Steps |  |
 |
|---|---|---|
| 10 | 4.013 | 2.73704 |
| 100 | 8.362 | 1.14085 |
| 1,000 | 25.248 | 1.01500 |
| 10,000 | 80.429 | 1.00686 |
| 100,000 | 252.274 | 0.99812 |
| 1,000,000 | 797.822 | 1.00001 |
The left column diverges. It grows roughly like  and has no limit — look closer at the path and you find more length, forever. A Brownian path has **infinite length over any interval**.
The right column converges, and not to something arbitrary:

The quadratic variation of Brownian motion over  equals
 exactly. Not approximately, not in expectation — the limit is deterministic. That is the strange and useful part: a random path has a completely non-random quadratic variation.
Compare with a smooth function
Do the same thing to  , the least exciting path imaginable:
| Steps |  |
 |
|---|---|---|
| 10 | 1.000 |  |
| 1,000 | 1.000 |  |
| 100,000 | 1.000 |  |
Exactly reversed. Finite total variation, and quadratic variation collapsing to zero.
That is the general rule: **any differentiable path has zero quadratic variation, and any path with non-zero quadratic variation cannot be differentiable.** The two properties are incompatible. Brownian motion has 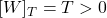 , so it is nowhere differentiable — not as a curiosity, but as an immediate consequence of the table above.
The reason is a one-line argument. Over a step of size  , a smooth function moves about
 , so squaring gives
 and summing
 of them leaves
 , which vanishes. Brownian motion moves about
 , so squaring gives , and summing of them gives , which does not.
This is where  comes from
Every treatment of Itô calculus hands you the rule

usually with the reassurance that it can be made rigorous. It is exactly the statement  , written differentially. The table above is the rigorous version, empirically.
And this single fact is the entire content of Itô’s lemma. In ordinary calculus, expanding  to second order gives
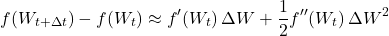
and you discard the second term as negligible. For a smooth path you may — the  terms sum to zero. For Brownian motion you may not, because they sum to . Keeping that term gives
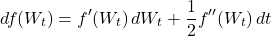
The  correction that distinguishes stochastic from ordinary calculus is quadratic variation, and nothing else. Once you have seen the second column of that first table, Itô’s lemma stops being a rule to memorise.
What it looks like for a general process
For an Itô process 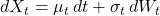 , the drift contributes nothing — it is smooth — and only the diffusion survives:
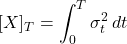
Quadratic variation scales with the **square** of volatility, and it is completely blind to drift. Checking on Brownian motion scaled by a constant  :
|
Measured  |
 |
|---|---|---|
| 0.10 | 0.00998 | 0.01000 |
| 0.20 | 0.03994 | 0.04000 |
| 0.40 | 0.15975 | 0.16000 |
Two consequences worth holding on to. Quadratic variation measures volatility and only volatility — you cannot learn anything about expected return from it, however finely you sample. And it is **observable**: unlike drift, which needs decades of data, quadratic variation can be estimated from a single path as finely as your data allows.
How accurately can you measure it?
That last claim needs a number, because “observable” is not the same as “free”.
The estimator over steps has standard deviation  . Measuring across 4,000 independent paths:
| Steps | Mean | Measured sd | |
|---|---|---|---|
| 10 | 0.99882 | 0.44813 | 0.44721 |
| 100 | 0.99662 | 0.14077 | 0.14142 |
| 1,000 | 1.00005 | 0.04475 | 0.04472 |
| 10,000 | 1.00017 | 0.01433 | 0.01414 |
Unbiased at every resolution, and the error falls like  — so it depends on **sampling frequency**, not on calendar span.
That is the exact opposite of the drift, whose standard error is  and improves only with more years of data. Sample a stock every minute for a month and you will have a sharp volatility estimate and learn essentially nothing about its expected return. This asymmetry is why implied volatility markets exist and “implied drift” markets do not, and quadratic variation is the reason for it.
Where it shows up in practice
**Realised volatility** is quadratic variation with a different name. Sum squared five-minute log returns over a day and you have estimated  for that day. The whole realised-volatility literature is applied quadratic variation.
**Variance swaps** pay the realised variance of the log price, which is 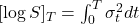 . The payoff *is* a quadratic variation, which is why variance swaps can be replicated with a static portfolio of options while volatility swaps cannot — variance is the natural object, volatility is its square root and does not add.
**Lévy’s characterisation** says a continuous martingale  with
 and
 *is* a Brownian motion. Quadratic variation is enough to pin down the process entirely, which makes it the standard tool for proving something transformed is still Brownian.
**And in practice, it is how you validate a simulation.** If you have written a discretisation of an SDE, sum the squared increments and compare with  . Wrong by a factor of two and you have a
 where you need
 . Drifting steadily off and your volatility function is being evaluated at the wrong point in the step. It is a sharper diagnostic than checking means, because it is insensitive to drift errors.
Code
import numpy as np

T = 1.0

def variations(n, seed=3):
    rng = np.random.default_rng(seed)
    dW = np.sqrt(T/n)*rng.standard_normal(n)
    return np.abs(dW).sum(), (dW**2).sum()

for n in (10, 1_000, 100_000, 1_000_000):
    tv, qv = variations(n)
    print(f"n={n:>9,}   sum|dW| = {tv:>8.3f}   sum dW^2 = {qv:.5f}")

# the estimator is unbiased, with sd sqrt(2/n)
for n in (100, 10_000):
    rng = np.random.default_rng(11)
    est = ((np.sqrt(T/n)*rng.standard_normal((4000, n)))**2).sum(axis=1)
    print(f"n={n:>6}  mean {est.mean():.5f}  sd {est.std(ddof=1):.5f}"
          f"  theory {np.sqrt(2/n):.5f}")
Run it on your own SDE discretisation. If  does not converge to
 , the scheme is wrong regardless of how sensible the paths look.
The takeaway
Quadratic variation is what survives when you square the increments instead of taking their size. For a smooth path it vanishes; for Brownian motion it equals exactly, which is simultaneously why Brownian paths are nowhere differentiable, why , and why Itô’s lemma carries a second-derivative term that ordinary calculus does not.
It measures volatility, ignores drift, and can be estimated from a single path to arbitrary precision given fine enough data — which is more than can be said for almost anything else in finance.
Worth reading alongside what a martingale actually is, since Lévy’s characterisation combines both ideas, and the Radon-Nikodym derivative — quadratic variation is the one thing a change of measure cannot alter, which is exactly why volatility is the same under both measures.
The Itô integral, the isometry and the numerical checks that tell you when a discretisation is trustworthy are worked through from the ground up in the course modules.
Get the Quant Reference Card — four pages covering stochastic calculus, measure change, the models you’ll meet, discretisation, rates, credit and XVA. Free.