Value at Risk is the number that sits at the top of every bank’s daily risk report, drives regulatory capital, and gets quoted in board meetings by people who could not define it.
It is also not a measure of risk, in a sense that can be made precise. Here is a portfolio where splitting a position across two independent issuers takes the 95% VaR from zero to fifty. Diversification, the one thing every risk framework is supposed to reward, made the reported number infinitely worse.
Start with what VaR actually is, then why that happens, and then the part that matters most in practice: how badly you can be wrong before anyone notices.
The definition
VaR answers one question: over a given horizon, what loss will not be exceeded with a given probability?
Formally, for a loss  and confidence level
 :
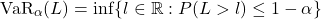
It is a quantile of the loss distribution, and it needs three inputs before it means anything:
| Input | Typical choice | Why it matters |
|---|---|---|
| Horizon | 1 day (trading), 10 days (regulatory) | Longer horizon, larger number |
| Confidence | 95%, 99% | Higher confidence, further into the tail |
| Distribution | Normal, historical, simulated | Where almost all the error lives |
“The one-day 99% VaR is 4.2 million” means: on 99 days out of 100, the loss should be smaller than 4.2 million. It says nothing whatsoever about the hundredth day.
The three ways to compute it
Parametric. Assume a distribution, usually normal, and read off the quantile: 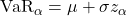 , with
 . Fast, transparent, and wrong in the tails, which is the only region it is being asked about.
Historical simulation. Apply the last  days of market moves to today’s portfolio and take the empirical quantile. Makes no distributional assumption, which is its appeal. The cost is that it can only produce losses that have already happened, and with 250 days of data the 99% quantile is determined by roughly the two or three worst observations in the sample.
Monte Carlo. Simulate from a model. The most flexible and the most dependent on model choices, which are now doing the work the data was supposed to do.
All three answer the same question. They disagree because the question is about a tail, and tails are where data is scarce and assumptions dominate.
What the definition does not say
VaR is a threshold, not an expectation. It marks the boundary of the tail and is silent about everything beyond it.
Two portfolios can have an identical 99% VaR of 10 million, where one loses at most 10.1 million in the worst case and the other loses 500 million. The reported number is the same. This is not a subtlety; it is the central structural property, and it is why selling deep out-of-the-money options is the classic way to produce a flattering risk report.
Expected Shortfall closes that gap by averaging over the tail rather than marking its edge. It is the mean of the worst  fraction of outcomes:
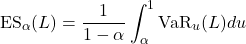
Worth noting in passing, because it is a common implementation bug: 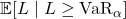 is not the same quantity. The two coincide only when the loss distribution is continuous. For the discrete example below they differ by a factor of twenty.
Hold that thought, because the next section is the reason regulators eventually switched to Expected Shortfall.
Diversification can make VaR worse
A risk measure  is subadditive if
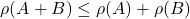
In words: combining two positions cannot produce more risk than holding them separately. This is the formal statement that diversification helps, and it is one of the four axioms of a coherent risk measure. VaR does not satisfy it.
Here is the smallest counterexample I know, and it is not contrived — it is a corporate bond book.
Take a bond with face 100 and a 4% chance of defaulting to zero recovery. The loss is 100 with probability 4% and zero with probability 96%. Now ask for the 95% VaR. Since 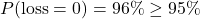 , the 95th percentile of the loss distribution is zero.
Now diversify. Hold 50 of face in each of two independent issuers, each with the same 4% default probability. Same total exposure, same credit quality, two names instead of one.
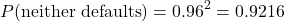
That is below 95%, so the 95th percentile now lands inside the region where one issuer has defaulted. The 95% VaR is 50.
| Portfolio | VaR 95% | ES 95% |
|---|---|---|
| 100 in one issuer | 0.00 | 80.00 |
| 50 + 50 in two issuers | 50.00 | 51.60 |
d1 = rng.random(M) < 0.04
d2 = rng.random(M) < 0.04
lossA = 100*d1                 # concentrated
lossB = 50*d1 + 50*d2          # diversified
np.quantile(lossA, 0.95)       # -> 0.0
np.quantile(lossB, 0.95)       # -> 50.0
Stated as the axiom, with  and
 the two 50-face positions:
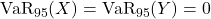 , because each defaults with probability 4% and the 95th percentile sits below that. But
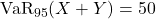 . The combination carries more measured risk than the sum of its parts, which is the violation written out in full.
A risk manager optimising the reported 95% VaR would concentrate the entire book in a single name. That is not a perverse reading of the number. It is the number working exactly as defined.
Two things make this less alarming and more interesting than it first appears.
First, the failure is specific to the confidence level. At 99% the ordering reverses: the concentrated book has  against 50 for the diversified one, because 4% now exceeds the 1% tail and the single default is inside it. The violation does not say diversification is bad. It says the quantile is a discontinuous function of the portfolio and can move in either direction.
Second, Expected Shortfall gets it right. 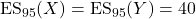 , summing to 80, against
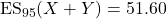 . The inequality points the right way, and the concentrated book is correctly reported as the riskier of the two at both confidence levels: 80 against 51.60 at 95%, and 100 against 58 at 99%. ES is subadditive, always, and the contrast in that table is the whole argument for the Basel Committee’s move to Expected Shortfall under FRTB.
When VaR is well behaved
Worth being fair to it. For elliptical distributions — the normal being the obvious case — VaR is subadditive. Simulating two standard normal exposures at a range of correlations:
| Correlation | Sum of individual VaRs | VaR of the combination |
|---|---|---|
| 0.0 | 2.3263 | 1.6440 |
| 0.5 | 2.3268 | 2.0134 |
| 0.9 | 2.3261 | 2.2678 |
Diversification helps in every row, as it should. So an equity desk with roughly symmetric, roughly elliptical P&L is not being misled by VaR in this particular way.
The failure needs asymmetry and discreteness — the jump-to-default structure above, or anything with a small probability of a large discrete loss. Credit, insurance, structured products, written options, operational risk. The books where VaR breaks are exactly the books where the tail is the point.
How wrong can a VaR model be before anyone finds out
This is the part I would put first if the search engine allowed it.
A 99% VaR model is validated by counting exceptions: days when the realised loss exceeded the forecast. Over 250 trading days you expect 2.5. The Kupiec test asks whether the observed count is consistent with 1%.
Run the binomial arithmetic. With 250 days at a claimed 1%, the smallest exception count that rejects the model at the 5% significance level is six. Basel’s traffic light is looser still: the green zone runs from zero to four exceptions, yellow from five to nine, red at ten or more.
Now ask the question a validator should ask, which is not “does the test reject a correct model” but “does it catch an incorrect one”:
| True breach rate | How wrong | P(test rejects) | P(lands in Basel green) |
|---|---|---|---|
| 1.0% | correct | 0.041 | 0.892 |
| 1.5% | 50% too risky | 0.176 | 0.678 |
| 2.0% | twice as risky | 0.384 | 0.439 |
| 2.5% | 2.5 times | 0.596 | 0.249 |
| 3.0% | three times | 0.763 | 0.128 |
| 5.0% | five times | 0.987 | 0.005 |
Read the third row. A model whose true breach rate is double what it claims is detected 38% of the time, and spends 44% of its years sitting comfortably in the green zone. A model three times too risky still shows green more than one year in eight.
The reason is not a flaw in the test. It is that 250 observations of a 1% event contain about two and a half events, and you cannot estimate a rate from two and a half observations. This is the same wall that makes expected returns unestimable from decades of data: tail quantities need sample sizes nobody has.
The practical implication for anyone doing model validation: a clean backtest is weak evidence. It is consistent with a correct model and roughly equally consistent with a badly broken one. Conclusions have to come from somewhere else — the construction of the model, the stability of its inputs, how it behaves in stress periods — and the exception count is a sanity check, not a verdict.
One criticism that does not survive the numbers
The standard complaint about scaling a one-day VaR to ten days by multiplying by  is that it understates risk, because returns have fat tails. I ran it, expecting to confirm it, and it is wrong in the direction everyone assumes.
| Return process | Error of the  rule |
|---|---|
| iid normal |  |
iid Student- , 6 df |
overstates by  |
GARCH(1,1),  ,  |
understates by  |
GARCH(1,1),  ,  |
understates by  |
With iid fat tails the rule is conservative, not aggressive, and by a wide margin. The reason is the central limit theorem: summing ten draws pulls the distribution towards normality, so the ten-day distribution has relatively thinner tails than ten one-day distributions scaled up. Volatility clustering pushes the other way, as expected, but by under two percent.
So the rule is a minor approximation error sitting next to a subadditivity failure and a backtest with 38% power. It attracts criticism because it is the only part of the calculation simple enough to criticise precisely. Spend the attention elsewhere.
What to do with all this
Report Expected Shortfall alongside VaR. It is coherent, it sees the whole tail, and it is what FRTB requires anyway. Keep VaR for continuity and for the backtest, which is easier to run on a quantile.
Never optimise a portfolio on VaR directly. The counterexample above is what the optimiser will find, and it will find it faster than you will.
Check how your ES is implemented. If the code computes 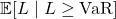 rather than the mean of the worst tail, it is right for continuous distributions and wrong for discrete ones — and credit books are discrete. In the example above that shortcut returns 4.01 instead of 80.
Treat VaR as a conversation starter. The number is a threshold with a confidence level attached. The useful questions are what sits beyond it, how the model behaved in the last three stress episodes, and what the exception count would look like if the model were twice as bad — which, per the table, looks much the same.
The honest caveats
The bond example uses independent defaults, and real credit portfolios have correlated ones. Correlation does not rescue VaR here; it generally makes subadditivity violations easier to construct, not harder, because it thickens the joint tail. But the clean 0-versus-50 contrast is a product of the idealisation, and a real book would show something messier.
Expected Shortfall is coherent, which does not make it easy. It is harder to backtest than VaR — it is not elicitable in the same way a quantile is — and it is more sensitive to the tail assumptions you were least confident about to begin with. Trading a measure with a known axiomatic defect for one with a known estimation defect is a real trade-off, not a free upgrade.
And the backtest power figures assume iid exceptions. Real exceptions cluster, which makes the independence part of the test informative too, and conditional coverage tests exploit that. They have more power than the plain count, and still not much.
The same sample-size wall appears in a different guise when estimating expected returns, where 400 years of data are needed to pin a drift to one percentage point.
Risk measures, their axioms and the validation tests that are supposed to catch a broken model are worked through from the ground up in the course modules.
Get the Quant Reference Card — four pages covering stochastic calculus, measure change, the models you’ll meet, discretisation, rates, credit and XVA. Free.