The Cox-Ingersoll-Ross process is the standard answer to a standard complaint about Vasicek: the short rate should not go negative, and CIR’s  diffusion term shuts off the volatility as the rate approaches zero. The boundary is respected. That is the selling point.
Then you discretise it, and 88% of your paths go negative.
The instinct at that point is to take the absolute value. That single line of code moves the five-year zero-coupon yield by 316 basis points and misprices a caplet by 129%. It is the worst of the four available fixes, and it is the one almost everyone reaches for first.
Where the guarantee comes from, and where it goes
The process is
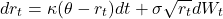
Strict positivity is not free. It holds when the Feller condition is satisfied:

When the inequality is strict, zero is inaccessible: the mean reversion pushing up from below dominates the diffusion, and the process never reaches the boundary. When the inequality fails, zero is attainable — the continuous process touches zero, and is then reflected back into positive territory.
Two things are worth separating here. Even when the continuous process is strictly positive, the Euler discretisation of it is not. The discrete step is a Gaussian increment with standard deviation  , and a Gaussian has support on the whole real line. Whenever
 is small, there is always a
 that takes you below zero. The next step then requires
 with
 , and the simulation either produces a complex number or a
nan, depending on how your language handles it.
So the positivity guarantee is a property of the continuous process. It is not inherited by the scheme.
How often this happens
Take a calibration that violates Feller comfortably:  ,
 ,
 ,
 , five-year horizon. Then
 against
 , so the ratio
 is
 . Two hundred thousand paths.
| Time step | Paths that go negative at least once |
|---|---|
| Monthly (12 steps) | 88.07% |
| Weekly (52 steps) | 92.51% |
| Daily (252 steps) | 93.56% |
Read that column again. Refining the time step makes it worse. This is the opposite of what discretisation intuition suggests, and the reason is simple once stated: each step is another opportunity to cross the boundary, and the process spends a great deal of its time loitering near zero. Finer steps take smaller excursions but take far more of them. You cannot escape this by refining.
The figure is not a rounding artefact from an aggressive calibration either. With Feller comfortably satisfied —  , ,
 , ratio
 — monthly steps still send 18.80% of paths negative. Less than one in five rather than nine in ten, but not zero.
The four fixes, and what each costs
All four appear in production code. I priced the same five-year zero-coupon bond under each, which is the right test because CIR has a closed-form bond price to compare against:
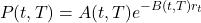
For these parameters the analytic price is  , a yield of 352.6 bp. Errors below are in basis points of yield, so positive means the scheme overstates the yield and undervalues the bond.
| Scheme | Monthly | Weekly | Daily |
|---|---|---|---|
| Partial truncation |  |
 |
 |
| Full truncation |  |
 |
 |
| Absorption at zero |  |
 |
 |
| Reflection |  |
 |
 |
| Exact sampling |  |
 |
 |
The two schemes that enforce positivity are the two that fail. Reflection — 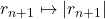 — is off by 316 bp at monthly steps and is still off by 85 bp at daily steps. Absorption, which clamps at zero, is off by 132 bp and still 42 bp daily. These are not convergence-rate problems you can spend your way out of. Both schemes are consistently biased, and the bias decays so slowly that no realistic step count rescues them.
The mechanism is worth stating plainly, because it generalises beyond CIR. Both fixes manufacture rate. Reflection takes a rate that wanted to be  and reports
 ; absorption reports
 instead of . Every intervention adds interest that the model did not generate. Those additions accumulate inside
 , the discount factor comes out too small, and the yield comes out too high. The scheme is not approximating CIR. It is simulating a different, higher process that happens to share CIR’s parameters.
The two truncation schemes do the opposite: they leave negative in the drift and the integral, and only guard the square root. Partial truncation uses  in the diffusion while keeping the raw in the drift; full truncation replaces with
 in both places.
rp = np.maximum(r, 0.0)

# partial truncation: raw r in the drift
r_next = r + k*(th - r)*dt  + sig*np.sqrt(rp)*np.sqrt(dt)*z

# full truncation: truncated r in the drift as well
r_next = r + k*(th - rp)*dt + sig*np.sqrt(rp)*np.sqrt(dt)*z
The trap in that table
Partial truncation looks like the winner. It is off by 9 bp at monthly steps where full truncation is off by 71. If you were choosing a scheme from the bond price alone, you would pick it.
Now test the same four schemes on the mean of the terminal rate, where the exact answer is 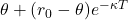 , which for
 is exactly 4%. And then on a caplet-style payoff
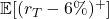 , whose exact value under the noncentral chi-square law of
 is
 .
| Scheme | Error on  , monthly |
Caplet error, monthly | Caplet, daily |
|---|---|---|---|
| Partial truncation |  bp |
 |
 |
| Full truncation |  bp |
 |
 |
| Absorption |  bp |
 |
 |
| Reflection |  bp |
 |
 |
Partial truncation nails the mean to within a twentieth of a basis point, and misprices the caplet by 19%. Full truncation misses the mean by 93 bp, and misprices the caplet by 6.5% — three times better on the thing that matters.
The reason partial truncation gets the mean right is structural, not a sign of accuracy. Its drift term is  with the raw , which is exactly linear, so taking expectations of the recursion reproduces the exact ODE for
 regardless of what the diffusion term is doing. The mean is correct by construction even when the distribution around it is badly wrong. Full truncation breaks that linearity by using in the drift, which is precisely why its mean drifts — and precisely why its distribution is better behaved.
The practical consequence is a validation lesson. A scheme that reproduces the analytic mean has told you nothing about whether it reproduces the analytic distribution. If your model validation checklist for a short-rate simulator consists of matching first moments against closed form, partial truncation passes cleanly while carrying a 19% error on an option struck 200 bp out of the money. Test a convex payoff, or test a quantile.
You probably do not need a scheme at all
CIR has a known transition law. Conditional on  , the rate at
 is a scaled noncentral chi-square:
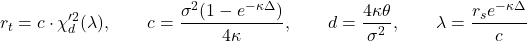
Sampling from that is one call to a standard library. It is exact at any step size, it is positive by construction, and it needs no fix because there is nothing to fix. The exact row in the first table sits within a basis point of analytic at every step count, including monthly.
from scipy.stats import ncx2

d   = 4*k*th/sig**2
c   = sig**2*(1 - np.exp(-k*dt))/(4*k)
lam = r*np.exp(-k*dt)/c
r   = c*ncx2.rvs(d, lam, random_state=rng)
The cost is that noncentral chi-square sampling is slower per step than a Gaussian increment, and that exact sampling of  does not by itself give you an exact , which still has to be approximated on the sampled path. For a bond price that integral is what you need, and the discretisation error re-enters there. But it re-enters as a clean quadrature error on a correctly distributed path, not as a structural bias from tampering with the state.
What to take away
Check  against
 before anything else, and log the ratio somewhere visible. Calibration routines wander into the violating region without announcing it, and the same code that is fine on Monday’s parameters is producing 88% negative paths on Tuesday’s.
Never reflect and never absorb. They are the two interventions that look like they are protecting the model and are in fact replacing it.
Default to full truncation when you need a discretisation scheme. It has the best distributional behaviour of the Euler variants and it converges cleanly. Use exact noncentral chi-square sampling when the payoff depends on the terminal distribution, which is most of the time for caps, floors and swaptions.
And count the negatives. An assertion that fires when any path goes below zero costs nothing and turns a silent bias into a visible one.
The honest caveat
Every number here is for one parameter set, one horizon and two payoffs. Full truncation is the standard recommendation in the literature and my results are consistent with it, but the ordering of the Euler variants on any particular payoff depends on how the discretisation error interacts with the shape of that payoff. Partial truncation beating full truncation on the bond price while losing badly on the caplet is not a paradox; it is the same phenomenon that makes a single test insufficient.
The conclusions that do generalise are the ones with a mechanism behind them: enforcing positivity by reflection or absorption adds rate that the model never produced, refining the time step increases rather than decreases the number of boundary crossings, and matching a first moment is not evidence of a correct distribution.
The bond price the schemes are being measured against is a discounted expectation, which is the correspondence Feynman-Kac makes exact. The same discretisation question, asked about a different model, produces the opposite answer in Euler versus Milstein.
Short-rate models, the schemes used to simulate them and the validation tests that catch a biased one are worked through from the ground up in the course modules.
Get the Quant Reference Card — four pages covering stochastic calculus, measure change, the models you’ll meet, discretisation, rates, credit and XVA. Free.