The usual answer is that above 1 is good, above 2 is excellent, and above 3 is exceptional.
I generated ten thousand trading strategies with mathematically zero edge — pure noise, no signal, nothing to find — and backtested each over five years of daily data. The best one came back with a Sharpe ratio of 1.70.
It was not a good strategy. There was no strategy. The number is the maximum of ten thousand draws from a distribution centred on zero, and that is the only thing it measures.
So the honest answer to the question in the title is that a Sharpe ratio on its own cannot tell you whether something works. What it can tell you depends entirely on three things nobody reports alongside it: how long the sample was, how many attempts preceded it, and what shape the return distribution has.
The definition
The Sharpe ratio is excess return per unit of volatility:

Daily or monthly figures are conventionally annualised by multiplying by the square root of the number of periods —  for daily,
 for monthly. Hold on to that convention, because one of the sections below is about where it breaks.
That is the whole formula. Its appeal is that it collapses a return stream into a single comparable number. Its problem is the same thing.
Nobody reports the error bar
A Sharpe ratio computed from data is an estimate, and estimates have standard errors. For returns that are independent and normal, the standard error of an estimated Sharpe is
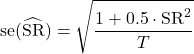
with  the number of observations. Annualised, for a strategy whose true Sharpe is 1.0:
| Track record | Standard error |
|---|---|
| 1 year |  |
| 3 years |  |
| 5 years |  |
| 10 years |  |
| 20 years |  |
Read the five-year row. A reported Sharpe of 1.0 after five years carries a 95% confidence interval of roughly  .
**That interval contains zero.** Five years of daily data, a Sharpe of 1.0, and you cannot reject the hypothesis that the manager has no skill whatsoever. It takes about six years of daily returns before a true Sharpe of 1.0 becomes statistically distinguishable from nothing at the 5% level — and that is assuming the true Sharpe was constant throughout, which it never is.
The number that should worry you more
The confidence interval above describes one strategy tested once. Nobody tests one strategy once.
So I ran the experiment properly. Generate  return streams with mean exactly zero. No edge, no signal, nothing but noise. Compute the Sharpe of each over five years of daily data. Keep the best one, which is what a researcher does when they report the strategy that worked.
| Strategies tried | Median best Sharpe | 90th percentile |
|---|---|---|
| 1 |  |
 |
| 10 |  |
 |
| 100 |  |
 |
| 1,000 |  |
 |
| 10,000 |  |
 |
Ten attempts is enough to produce a Sharpe of 0.69 from nothing. A hundred attempts gets you past 1.0, which is the threshold most people treat as evidence of a real edge. Ten thousand attempts gets you 1.70.
And the growth is relentless but slow, which is what makes it dangerous. Extrapolating the maximum of draws:
| Strategies tried | Expected best Sharpe from noise |
|---|---|
| 10,000 |  |
| 50,000 |  |
| 200,000 |  |
| 1,000,000 |  |
Fifty thousand sounds like an absurd number of backtests until you count the way a parameter sweep actually counts. Five parameters with ten plausible values each is one hundred thousand combinations, and running that grid is an afternoon. **A researcher who optimises five parameters over a grid has, without any intent to deceive, bought themselves a Sharpe of 2 from pure noise.**
This is why the number alone is uninformative. A Sharpe of 2 from a single pre-registered hypothesis is remarkable. The same 2 from the top of a parameter sweep is the expected value of the null. The two are indistinguishable in the number and completely different in meaning, and only one of them is ever disclosed.
Sharpe is blind to the shape of the distribution
The ratio uses the mean and the standard deviation. Nothing else. Skewness and kurtosis do not enter, which means a strategy that makes a small amount reliably and loses catastrophically on rare occasions scores extremely well right up until it does not.
I simulated a short-volatility book: small noisy premium collected most days, with a large loss arriving on average once every three years. Ten-year track records, six thousand runs.
| Measurement | Value |
|---|---|
| True Sharpe (median across all runs) |  |
| Runs that saw no tail event in 10 years |  |
| Median Sharpe in those quiet runs |  |
| Median skewness |  |
| Worst single day |  |
The strategy’s honest Sharpe is 0.51. But 3.4% of ten-year periods contain no tail event by luck alone, and in those the reported Sharpe is **2.54**.
Now think about which track records you actually see. The managers who hit two tail events closed. The ones running the identical strategy who happened to miss them are the ones raising capital with a decade-long Sharpe of 2.5 and a smooth equity curve. **The selection is doing the work, not the skill**, and the Sharpe ratio is structurally incapable of distinguishing them.
For comparison: a normally distributed strategy with the same true Sharpe has a skew near zero and a worst day around  . Same single number, twenty-two times the daily tail.
And the annualisation can be wrong too
Multiplying a monthly Sharpe by assumes returns are independent across periods. When they are autocorrelated — which happens whenever returns are smoothed, whether through illiquid marks, stale pricing or model-based valuations — the rule overstates.
Twenty years of monthly returns, AR(1) with coefficient  :
|
rule |
Actual annual Sharpe | Inflation |
|---|---|---|---|
 |
|
 |
 |
 |
|
 |
 |
 |
 |
 |
 |
 |
|
 |
 |
At a monthly autocorrelation of 0.4 — unremarkable for a credit or private-assets book — the conventional annualisation inflates the headline Sharpe by 44%. At 0.6 it nearly doubles it. No deception is required anywhere; it is the standard formula applied to returns that violate its one assumption.
So what is a good Sharpe ratio?
The best honest answer I can give:
**Below 0.5** is not distinguishable from nothing on any realistic sample.
**Around 1.0** is a plausible long-run figure for a genuine, well-diversified strategy. It needs about six years of daily data before it separates from zero, and it should make you ask how many variants were tried.
**Above 2** sustained over a long period, with a pre-registered hypothesis and no parameter sweep behind it, is genuinely rare and worth attention. The same number out of a backtest is the expected maximum of a moderate grid search and carries no information at all.
**Above 3 from a backtest** is evidence of overfitting, not of edge. It is easier to produce by searching than by finding.
The thresholds are not the point. **The point is that the number is uninterpretable without the three things that never accompany it**: the length of the sample, the number of attempts, and the shape of the distribution.
What to ask instead
How many variants were tested before this one? This single question does more work than any statistical correction. If the answer is “a few hundred”, apply the table above and recalibrate.
What is the skewness, and what was the worst day? Two numbers, both trivial to compute, and together they catch the option-selling profile that Sharpe cannot see.
Is the series autocorrelated? If yes, the annualisation is inflated and the correct adjustment is available.
And if the strategy is quantitative and the number came from a search, use the deflated Sharpe ratio, which adjusts explicitly for the number of trials and for non-normality rather than pretending they were absent.
The honest caveats
The overfitting simulation uses independent noise streams, and real candidate strategies are correlated with each other. Correlation reduces the effective number of independent trials, so the true inflation from a parameter sweep is somewhat smaller than the table suggests — a thousand variations of one idea is not a thousand independent attempts. The effect is large and real; the exact multiplier depends on how much genuine diversity there was in the search.
The standard error formula assumes independent normal returns, which is the assumption the autocorrelation section then demonstrates is often false. Where returns are autocorrelated or fat-tailed the true standard error is larger than quoted, so the confidence intervals above are optimistic rather than conservative.
And none of this says the Sharpe ratio is useless. It is the right tool for comparing two strategies with similar return shapes over the same period, and it is the correct objective in a mean-variance world. The failure is in reading it as a scalar measure of quality across strategies with different shapes, different sample lengths, and different numbers of attempts behind them.
The same wall appears when estimating expected returns directly, where 400 years of data are needed to pin a drift to one percentage point — and the Sharpe ratio has that same unestimable quantity in its numerator. For the blindness to tail shape, the Value at Risk version of the problem is the closest relative.
Performance measurement, backtest design and the statistics that tell you whether a result is real are worked through from the ground up in the course modules.
Get the Quant Reference Card — four pages covering stochastic calculus, measure change, the models you’ll meet, discretisation, rates, credit and XVA. Free.