A variance swap pays the difference between realised variance and a strike agreed at inception:
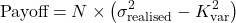
It is the cleanest way to take a view on volatility without taking a view on direction. And the reason it exists in this form — variance rather than volatility — is not a convention. It is the only version that can be replicated.
Realised variance is quadratic variation
Realised variance is defined as the annualised sum of squared log returns:
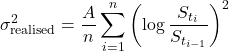
That sum is the quadratic variation of  . Which means the payoff of a variance swap is a quadratic variation — an object that, for an Itô process, is
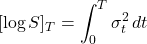
Simulating 400,000 paths with 25% volatility over one year, daily observations:
| Quantity | Value |
|---|---|
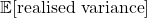 |
0.062492 |
 |
0.062500 |
| Fair strike in vol terms | 24.9983% |
The fair strike is the expected quadratic variation, and it recovers the input volatility to two basis points.
Note what does **not** appear: the drift. Quadratic variation is blind to it, so a variance swap is a pure volatility instrument with no directional exposure at all — not approximately, but structurally.
Why variance and not volatility
The obvious product would be a volatility swap, paying 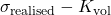 . It is more intuitive and it is much harder to price, for one reason: **variance adds, volatility does not.**
Variance over two periods is the sum of the variances. Volatility over two periods is not the sum of the volatilities. That additivity is what makes variance replicable and volatility not.
And the two are not related by a square root, because expectation and square root do not commute. From the same simulation:
| Value | |
|---|---|
 — variance swap strike |
0.249983 |
 — volatility swap strike |
0.249734 |
| Convexity gap | 2 bp of vol |
By Jensen’s inequality the volatility swap strike is always below the variance swap strike, and the gap widens with the volatility of volatility. Two basis points here under constant volatility; under a stochastic-volatility model with realistic vol-of-vol it runs into the tens of basis points. That **convexity adjustment** is precisely why volatility swaps require a model and variance swaps do not.
The replication, which is the elegant part
A variance swap can be replicated with a **static portfolio of vanilla options** — bought once at inception, never rebalanced — plus a dynamic position in the underlying.
The argument comes from Itô. Applying the lemma to :
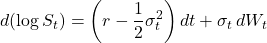
Rearranging to isolate the variance:
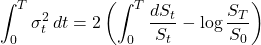
Two pieces. The first,  , is a dynamic position holding
 units of stock — continuous rebalancing, but a simple rule. The second is a **short log contract**, and a log payoff can be decomposed exactly into a strip of out-of-the-money puts and calls weighted by
 .
So realised variance is replicable from instruments that already trade. That is why the VIX is computed from a strip of SPX options — the VIX methodology is this replication, made into an index.
Where the theory meets the desk
Three places where the clean picture breaks, and they all matter.
**The strip is not infinite.** Replication requires options at every strike from zero to infinity. Real markets quote a finite range, so the far wings are missing, and that truncation biases the strike downward — more so for indices with steep skew. A quoted variance swap is always a truncated replication.
**Jumps break it.** The replication argument relies on being continuous. A gap in the underlying makes realised variance jump in a way the option strip does not capture, and the hedge fails exactly when it is most needed. This is why variance swaps on single names carry an explicit cap — typically 2.5× the strike — while index variance swaps often do not.
**Discrete observation.** The theory uses continuous quadratic variation; contracts use daily closes. The difference is small for a year but becomes material for short-dated swaps, and it is a genuine source of P&L rather than a rounding error.
Code
import numpy as np

S0, r, sig, T, n, M = 100., 0.03, 0.25, 1.0, 252, 400_000
rng = np.random.default_rng(8); dt = T/n

logS = np.full(M, np.log(S0)); QV = np.zeros(M)
for _ in range(n):
    dl = (r - 0.5*sig**2)*dt + sig*np.sqrt(dt)*rng.standard_normal(M)
    logS += dl
    QV += dl**2                      # realised variance, path by path

print(f"E[realised variance] = {QV.mean():.6f}   (sigma^2 T = {sig**2*T:.6f})")
print(f"variance swap strike = {np.sqrt(QV.mean()/T):.4%}")
print(f"volatility swap      = {np.mean(np.sqrt(QV/T)):.4%}")
print(f"convexity gap        = "
      f"{1e4*(np.sqrt(QV.mean()/T) - np.mean(np.sqrt(QV/T))):.0f} bp")
The check worth building in: the mean realised variance must converge to  . If it does not, the discretisation is wrong — and it is a sharper test than comparing option prices, because it is insensitive to drift errors.
The takeaway
A variance swap pays realised variance against a fixed strike, and realised variance is the quadratic variation of the log price. That single identification explains everything else: why the product has no directional exposure, why it can be replicated statically from a strip of vanillas, and why the volatility version cannot.
The gap between the two — against — is Jensen’s inequality, and it is the reason one instrument is model-free and the other is not.
Rests directly on quadratic variation, which is what the payoff literally is, and on Itô’s lemma, which supplies the replication identity.
Quadratic variation, replication arguments and the numerical checks behind them are worked through from the ground up in the course modules.
Get the Quant Reference Card — four pages covering stochastic calculus, measure change, the models you’ll meet, discretisation, rates, credit and XVA. Free.