Ordinary calculus has a chain rule. Stochastic calculus has one too, and it carries an extra term that ordinary calculus does not. Itô’s lemma is that chain rule, and the extra term is the whole point.
Here is the cleanest way to see why it has to be there.
The calculation that fails
Take  and apply it to Brownian motion. Ordinary calculus says
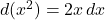 , so you would expect
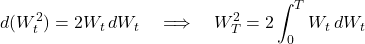
Both sides are computable. Simulating 200,000 paths with 20,000 steps each, over  :
| Quantity | Mean over paths |
|---|---|
 |
1.00158 |
 |
0.00157 |
| Difference | 1.00001 |
They are not equal. They differ by exactly  .
And the reason each side takes the value it does is worth noting. The Itô integral  is a martingale starting at zero, so its expectation is zero — and it is. Meanwhile
 , because
 is normal with variance . The gap between them is not noise; it is structural.
The correct statement is
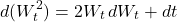
That  is the entire content of Itô’s lemma, in the simplest case anyone can check.
Where the extra term comes from
Expand  to second order:
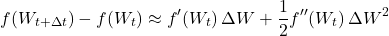
In ordinary calculus you discard the second term because  is negligible compared with
 . For a smooth path that is correct: the squared increments sum to zero in the limit.
For Brownian motion they do not. Brownian motion moves like  , so
 is of order
 — the same order as the terms you are keeping. Summing
 of them gives , not zero. This is exactly the statement that quadratic variation is non-zero, and it is written in shorthand as

Keep the second-order term instead of discarding it and you get the lemma.
The lemma
For  with
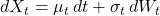 :
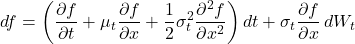
Everything except the  term is what ordinary calculus would give. That term is the correction, and note what it depends on: the **second derivative** of
 and the **square** of the volatility. Where is linear the correction vanishes entirely — which is why linear payoffs never need Itô.
The one everyone uses: geometric Brownian motion
With 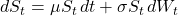 and
 :
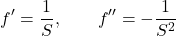
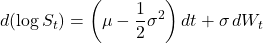
That  is why the solution to GBM is
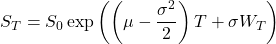
and not  . Every simulation of a stock price contains that correction, and getting it wrong is the single most common bug in a first Monte Carlo implementation — the paths look plausible and the mean comes out systematically too high.
The economic reading: **the log of the average is not the average of the log.** A stock with 12% expected return does not have 12% expected log return; it has  . With 20% volatility that is a 2 percentage point gap, and it compounds.
Where it matters in practice
**Black-Scholes falls out of it.** Apply Itô to an option value  , build a delta-hedged portfolio, and the
 terms cancel. What survives is the PDE, and the
 term in it is the Itô correction. Gamma appears in the pricing equation because of quadratic variation and for no other reason.
**Convexity is the same phenomenon.** Any time a convex function of a random variable is worth more than the function of the average — bond convexity, the volatility smile, gamma P&L — that is  doing the work.
**And the correction is zero where is linear.** Futures, forwards and swaps need no Itô adjustment. Options, bonds and anything with curvature do. That is a quick test for whether you need to think carefully about a payoff.
Code
import numpy as np

T, N, M = 1.0, 20_000, 200_000
dt = T/N
rng = np.random.default_rng(1)

W = np.zeros(M); naive = np.zeros(M)
for _ in range(N):
    dW = np.sqrt(dt)*rng.standard_normal(M)
    naive += 2*W*dW          # what ordinary calculus predicts for d(W^2)
    W += dW

print(f"W_T^2         = {(W**2).mean():.5f}")     # -> T
print(f"2*int W dW    = {naive.mean():.5f}")      # -> 0, it's a martingale
print(f"difference    = {((W**2)-naive).mean():.5f}")  # -> exactly T
Run it on your own SDE code as a check. If minus  does not converge to , something in the integration is wrong.
The takeaway
Itô’s lemma is the chain rule with a second-order term that ordinary calculus throws away and stochastic calculus cannot. The term exists because Brownian paths have non-zero quadratic variation, it is proportional to , and it vanishes exactly when the function is linear.
Every convexity effect in finance — the drift adjustment in GBM, gamma in the Black-Scholes PDE, bond convexity — is that one term appearing in a different costume.
Read alongside quadratic variation, which is the fact that makes the extra term necessary, and what a martingale is, since the Itô integral being one is what fixes the expectation in the calculation above.
The Itô integral, the isometry and the numerical checks that catch a broken implementation are worked through from the ground up in the course modules.
Get the Quant Reference Card — four pages covering stochastic calculus, measure change, the models you’ll meet, discretisation, rates, credit and XVA. Free.