Every Monte Carlo tutorial recommends antithetic variates. Pair each draw  with
 , average the two payoffs, and get a lower variance for free. It costs four lines of code and no thought.
On a straddle, it makes things worse. Not marginally worse. To match the accuracy of plain Monte Carlo you need 1.64 times as many paths. The variance reduction technique increased the variance by 66%.
Here is the number, and then the one-line condition that tells you in advance whether it will happen to you.
The setup
Geometric Brownian motion,  ,
 ,
 ,
 year. Four million paths. For each payoff I compute the discounted expectation twice: once from , once from , and then measure the correlation between the two payoff streams.
import numpy as np

rng = np.random.default_rng(12345)
S0, r, sig, T = 100.0, 0.02, 0.40, 1.0
Z = rng.standard_normal(4_000_000)

def ST(z):
    return S0 * np.exp((r - 0.5*sig**2)*T + sig*np.sqrt(T)*z)

def efficiency(payoff):
    a, b = payoff(ST(Z)), payoff(ST(-Z))
    rho = np.cov(a, b, ddof=1)[0,1] / a.var(ddof=1)
    return rho, 1.0/(1.0 + rho)
The second number returned is the efficiency ratio: the variance of plain Monte Carlo divided by the variance of the antithetic estimator, at an equal number of normal draws. That last clause is where most write-ups go wrong. Comparing “1,000 paths plain” against “1,000 antithetic pairs” compares two different amounts of work, and it flatters the technique.
The results
| Payoff |  |
Efficiency | Verdict |
|---|---|---|---|
Forward,  |
 |
6.80× | Excellent |
| Digital, |
 |
4.70× | Excellent |
| Call, |
 |
1.43× | Worth it |
Call,  |
 |
1.10× | Barely |
| Butterfly, 80/100/120 |  |
0.63× | Harmful |
Straddle,  |
 |
0.63× | Harmful |
| Straddle, |
 |
0.60× | Harmful |
The spread runs from a 6.8-fold improvement to a 40% degradation, on the same model, the same random numbers and the same code. The only thing that changed is the payoff.
I checked the straddle result empirically as well, rather than trusting the covariance algebra. Four thousand independent experiments of 20,000 normal draws each: the plain estimator had a standard error of 0.1947, the antithetic estimator 0.2497. Squaring the ratio gives the 1.64 factor. The theory and the experiment agree.
Why antithetic variates backfire
Write the discounted payoff as a function  of the standard normal driver. Plain Monte Carlo with
 draws has variance
 . The antithetic estimator spends the same draws on
 pairs:
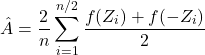
Its variance is not . Working through the algebra:
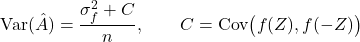
So the efficiency ratio is
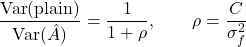
That single expression is the whole story. Antithetic sampling helps if and only if  . It does nothing at
 . It hurts whenever
 , and in the limiting case
 it doubles the variance exactly, because then
 and
 carry identical information and half your draws were wasted.
Check the table against the formula. The ATM straddle has  , and
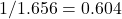 . The forward has
 , and
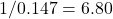 . No approximation involved.
The condition you can check before writing any code
There is a classical result: if is monotone, then 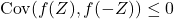 . Monotone payoffs are therefore always safe. Forwards, calls, puts, digitals, zero-coupon bonds, anything whose value only ever moves one way as the driver increases.
A straddle is not monotone. Its payoff  is large when the underlying moves a long way in either direction, which makes it close to an even function of . An even function satisfies
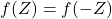 exactly, giving . The ATM straddle is not exactly even — lognormal asymmetry and the drift break the symmetry, which is why rather than
 — but it is even enough to lose you 40% of your compute.
So the rule is short. Monotone in the driver: use it. Not monotone: measure on a pilot run of ten thousand paths before committing. That pilot takes under a second and settles the question exactly.
Where this actually bites
The straddle is the clean teaching case, but it is not where the damage happens in production. Three places matter more.
Volatility products. Variance swaps, gamma swaps, corridor variance. Realised variance accumulates squared increments, and squaring destroys sign information. These payoffs are close to even by construction.
Butterflies and condors. Any strategy whose value peaks in the middle of the distribution and decays on both sides. The 80/100/120 butterfly above lands at  .
Delta-hedged books. This is the subtle one and the one worth remembering. The point of delta hedging is to remove first-order sensitivity to the driver. What remains is dominated by gamma, which is second-order, which means it is approximately quadratic in the driver, which means approximately even. A portfolio that has been carefully constructed to be insensitive to the sign of the move is a portfolio for which antithetic sampling has been carefully constructed to be useless.
If you inherit a risk system where antithetic sampling is switched on globally as a default, that default is being applied to hedged P&L distributions where it silently costs compute.
What to use instead
When comes back positive, the technique to reach for is control variates rather than a different symmetry trick. A control variate uses a correlated quantity with a known expectation, and for equity payoffs the underlying itself or a Black-Scholes-priced vanilla usually works. The mechanism is unrelated to the parity of the payoff, so the non-monotonicity that kills antithetic sampling does not affect it.
Stratified sampling and Brownian bridge constructions are also unaffected by payoff parity, though they interact with path dependence in their own ways.
What this result does not say
Three honest limits.
The numbers above are single-period European payoffs under a one-factor model. For a path-dependent payoff the driver is a vector, evenness in one coordinate does not imply evenness overall, and has to be measured rather than reasoned about. An Asian option, for instance, averages the path and inherits the monotonicity of the average, so it behaves more like a call than like a straddle.
The efficiency ratio is a variance statement, not a bias statement. Antithetic sampling is unbiased in every case above, including the ones where it hurts. You are not getting the wrong answer, you are getting the right answer more slowly.
And the 1.64 factor is specific to these parameters. Raise the volatility or lengthen the maturity and the lognormal asymmetry grows, which pulls down and softens the penalty. The sign of the effect is structural; the magnitude is not. That is exactly why the pilot run is the recommendation rather than a table of memorised factors.
The same class of silent Monte Carlo error appears in CIR discretisation, where a scheme that reproduces the analytic mean can still misprice a caplet by 19%, and in the choice between Euler and Milstein, where the higher-order scheme is 43 times better on one model and useless on another.
Variance reduction, discretisation and the diagnostics that tell you which technique is actually helping are worked through from the ground up in the course modules.
Get the Quant Reference Card — four pages covering stochastic calculus, measure change, the models you’ll meet, discretisation, rates, credit and XVA. Free.